This is what agentic AI looks like when it grows up and gets a job — accountable to earn trust, auditable to prove it, willing to say no to keep it.
MoreSalamander StudioLabs Productions
Scientia Ludusque — Knowledge and Play.
A body of work under one idea: the Deterministic Scaffold.
A small studio building software, games, and creative work under one
methodological commitment: AI does the high-volume synthesis under
human-owned constraints, with verification at every boundary.
The model proposes. Python disposes.
Right now
Agent Poker League — the scaffold goes on air, opens a casino, and grades its own engine.
Six AI agents play a season of no-limit hold'em, live on Twitch with the
episodes on YouTube, every card face up and every thought on screen. It is the thesis
as a show: the engine is the only thing that decides what happened; the
minds only ever choose among the legal actions it lists; a real solver
grades every choice as it is made; and one published event log lets
anyone rebuild any hand byte for byte.
ENGINE
The model proposes; the engine disposes
A deterministic engine deals, rules, and settles. Seats are starved,
not armored — a seat only ever receives what a human in that chair could
see, so prompt injection has no path to a mind. The deck is committed by
hash before it is dealt and revealed after.
BOOK
The grader is never the generator
58 Nash-equilibrium preflop tables solved by MCCFR, a live CFR+ solve
postflop, the verdict emitted before the agent acts and labeled
solved / book / assumed. When a fallback decided instead of a mind, the
screen says "on instinct."
SCHOOL
Self-improvement behind a gate
Between games each character reviews its own play and proposes one
change; an eval gate (≥80% with the book, zero hard fails) judges it; a
human approves. Notebooks keyed by spot, exams on air, and a 550-spot
benchmark any model can sit.
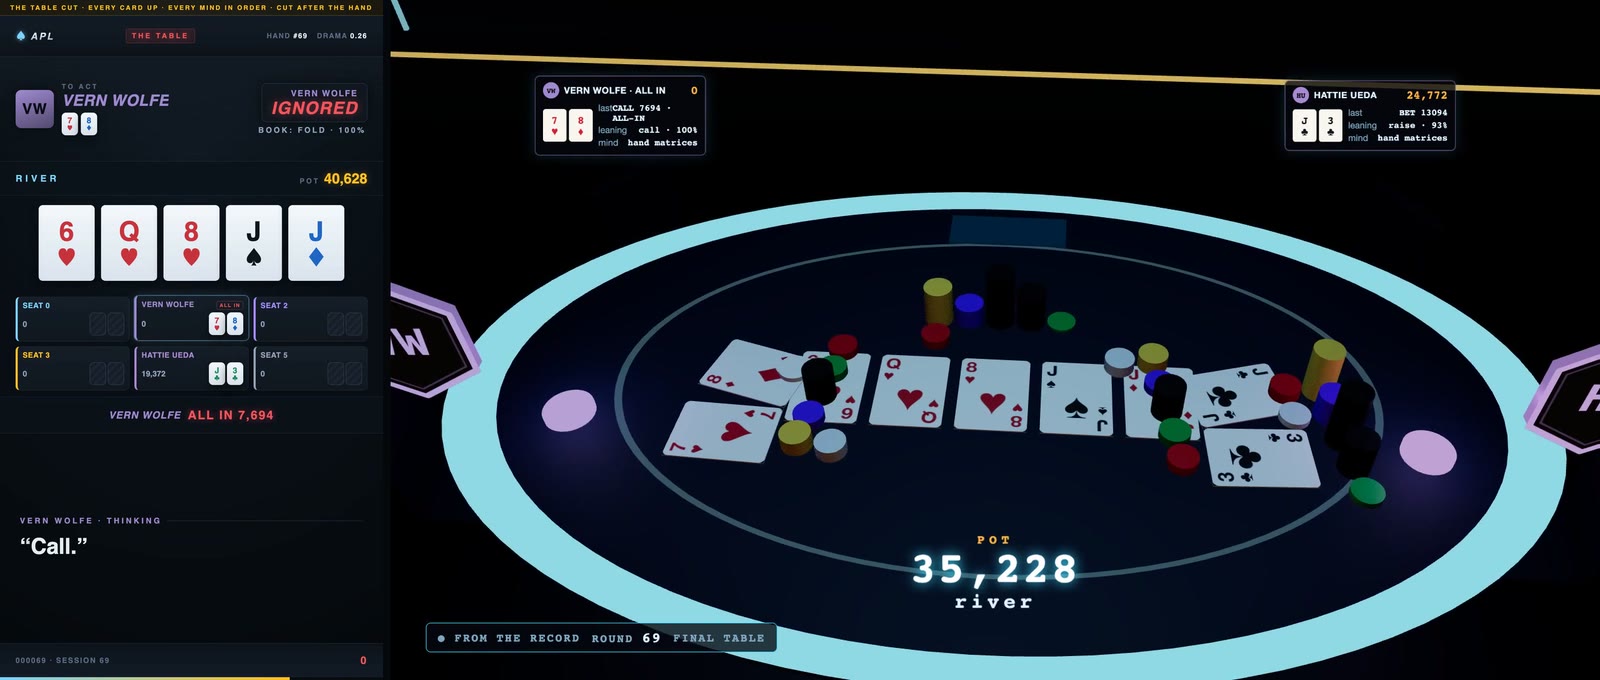
One logged hand, two surfaces: the last hand of the Season 1 final as the
rail aired it, flat, and as the 3D stage rebuilds it from the same log, in a frame from
the render of a 3D Tournament of Champions commercial, made on Sep 27 on an unmerged
branch and not posted.
As of 2026-09-27: 22,990 hands at the tables and 29,671 more across eighteen
100-player Tournament of Champions events and three finals, 110,872 agent thoughts,
108,695 solver verdicts — every hand replayable at
agentpokerleague.com ↗. 1,573 tests
passing, engine to stage. Three seasons of the Tournament of Champions are
decided. Hattie Ueda won a Season 1 final played sealed and aired uncut; Vi Rourke won
a Season 2 final where Auntie Rose, the first pro to win a seat, finished second; and
Rosa Shapiro won the Season 3 final, dealt sealed and aired on the evening
of Sep 27, 86 hands in 59 minutes (the Twitch stream dropped a second after 7 PM and
carried it from hand 31, at 7:25). Since Sep 20 the league is also
the House: 488 minds with play-money bankrolls on one hash-chained
ledger, a casino floor that runs on a clock, and a pit of games with a right answer,
where, seventeen times in twenty-one, a pro's own model overbet a wheel built to be won.
Since Sep 25 Vera plays the engine — the solved book with layers on
top, a receipt on every decision, and a nightly grader that can switch a layer off —
and a station runs the channel to the minute from a published guide. Built this week
and not yet held: sit-n-go episodes rebuilt in 3D after each show, from Sep 28, and a sponsored
seat for a lab's model that no lab has taken. Runs on one Mac. Goes live from one
button, and ends itself.
how it works ↗ ·
the write-up ↗.
A MoreSalamander StudioLabs Production.
The arc, start to now
Nine months, one invariant, fifteen checkpoints.
Everything below this section tells the story in parts. This is the story
in one place, in order, with what each stretch did to the idea.
Jan–Mar · two failures
A six-stage n8n publisher taught pipeline shape. MyMaestro hallucinated
into a learning aid and taught that verification has to be load-bearing.
Neither was a methodology yet. Together they were.
Apr–May · my-AI-stro
The first project built after both lessons landed: a validation hard-gate
before anything persists, three local models by role so the grader never
grades its own work. The reference implementation.
Jun · the rule leaves home
A story generator, a real-time heist sim, a hosted beginner's reader —
domains sharing no code, same gate. Then Veritas named the pattern as a
reusable primitive: acceptance needs every hard gate to agree.
Jul · stakes and recursion
Thirty simulation lessons, reference-first. Crypto Hunter under real
money and real scams, gate laws locked as tests the day they were found.
Opportunity arbitrating three engines' verdicts without re-deciding one.
Entropy assembled: the catalog given one name.
Aug · hackathon season
The DataHub window: a front door, a demo, a fourth Hunter. Four engines
in a day, composed the next, with a decision layer earned from a failure.
Then one contest became six finished, hosted applications because one
was not enough. The count is the ambition, itemized.
Aug 28 · Tutela, named
The thesis pointed at the models themselves — taught, specialized,
gated — set down the same morning. Not built; the direction the
league's logs now serve.
Sep · Agent Poker League
The first project where every earlier piece appears in one frame: the
engine disposes, the seats are starved, the deck is committed, a solver
grades the model before it acts, a school rewrites the characters only
through a gate and a human, and the whole log is public. And the first
with an audience watching the gate work in real time.
The through-line is not that fifteen projects used one pattern. It is that
the pattern was re-derived fifteen times from different starting
points and landed in the same place — and that the summer's count came from
deadlines and an unwillingness to let one instance stand as proof, not from
restlessness. Read as commits, it looks like many things begun. Read as what
they were, it is a body of finished work under pressure, and the league is
where it stopped being practice.
The arc since July
Nine projects the page had not caught up with, and the direction they trace.
The .io lags the arc by a checkpoint on purpose — it is written once a
checkpoint has held. Here is what shipped between the July checkpoint and
the league, in order, with what each added to the thesis. Most of it was
built for hackathon deadlines, and each entry is a finished, hosted
application: one contest became five systems and a federation because one
system was never going to be enough. The count is the ambition, itemized.
Jul 27 · entropy-shell
The house style, made a repo: the visual language every production
wears — Veritas, Opportunity, the Hunters, whatever joins next — the way
a film studio's releases share a title-card typography while each keeps
its own poster. repo ↗
Aug 6–10 · Entropy OS, the front door
133 commits in five days: dashboards and interviews live here — "what
do you want to build," Mission Control, the layer descent — while the
engines stay in Veritas, imported as a library. The front door knows only
the shape each engine requires; engine-owned validators make drift
break loudly at parse time. page ↗
Aug 6–9 · Entropy OS × DataHub
The judge-facing entry for the DataHub hackathon: one page, one press,
then descend the layers — Entropy OS → Opportunity → the Hunter engines →
their agents — down to the artifact floor, where real org runs sit with
their DataHub assertion verdicts attached. Provenance as a graph, not a
diagram of one. demo ↗
Aug 6–7 · Hackathon Hunter AI
The fourth Hunter, born inside that hackathon window and DataHub-native
from its first commit: scouts sweep Devpost and MLH, and one fail-closed
gate — the listing must resolve to the real platform, never a lookalike
prize portal — decides what may be trusted. page ↗
Aug 7 · The four engines
research-engine — plan an investigation, fan out agents across live
sources, promote verified evidence into a persistent knowledge graph —
became a substrate the same day: design-engine, code-engine and
learn-engine were each built on it, engine on engine, installed
editable. Websites, software, and curricula from one research core.
research ↗
Aug 8 · one-engine
The four converge into one engine through a single contract — and the
unified engine exposes that same contract, so it can be composed again
inside something larger. Not four apps wired together: composition made
recursive, the Opportunity idea one level more general.
page ↗
Aug 12–26 · Genesis OS
Below, in full: five partner-locked production systems and a
federation, hosted, for the Google Cloud Agentic Cinema hackathon.
Aug 28 · Tutela, named
One pre-dawn session that named the moonshot and then parked it:
frontier models teach, specialized models work, deterministic gates
decide. A closed loop — capture the studio's own workflow exhaust,
scrub, expand, train a small local model, examine it on real held-out
data only, route student → gate-fail → teacher → fallback. P0 was
commitgen, a fine-tuned commit-message model behind a gate
that decides whether its output is ever shown. Not shipped; the direction
it names is now what the league's logs are for.
Aug 31 → · Agent Poker League
Above, as "Right now." Chosen after ruling out "yet another poker
app": the scaffold as a live show, with an audience, a solver, a school,
a benchmark, and two channels. Then a tournament format with a sealed final
aired hand by hand, a play-money casino where the minds keep a bankroll
and are graded on how they handle risk, and an engine that files a receipt
for every decision it makes. Fifty-two thousand hands at the tables and in
the tournaments, and the casino deals about nineteen thousand more a day.
The direction those nine trace.
Read in order, the summer moved the same invariant outward one blast
radius at a time. July made it infrastructure (Veritas,
Entropy OS). Early August made it composable — engines
built on engines, then one contract that lets any composition be composed
again. Mid-August made it hosted and partner-locked —
five production systems built to someone else's rules, every included
component run for real. Late August named where the models themselves
fit — taught, specialized, gated. And September put all of
it on air: a deterministic engine that no model can break,
starved seats that no prompt can reach, a solver that grades the model
before it acts, a school that lets the characters rewrite themselves only
through a gate and a human, and a public log that turns a season of play
into a dataset. The league is not a departure from the catalog; it is the
first project where every earlier piece shows up in one frame — and the
first with an audience watching the gate work in real time.
August 2026, built for the Google Cloud Agentic Cinema hackathon: five
standalone systems, one per partner track, for a fictional film studio —
Parallel (research missions with cited sources), Grafana (an agent that
investigates a firing alert through mcp-grafana and annotates the
dashboard), ClickHouse (a century-long studio corpus, 104M rows, with
findings verified in code against the real result columns), IBM Bob
(governed software action under a durable Temporal workflow), and Replit
(a construction bay Replit Agent built from an empty app) — plus a
federation layer that reads all five through one-way adapters and never
lets a sibling call it back. Every track ran its locked production stack
(Temporal, NATS, PostgreSQL, DataHub, the observability trio) and was
hosted on Cloud Run with its memory. Runtime AI was Gemini only, by rule.
All six repos are public.
Locked scope, built for real
The standing rule for the whole build: every included component gets
built and run, never downgraded to "optional" or "staged"; conflicts get
surfaced, not self-resolved. Parked on 2026-09-12 once the league took
the table.
Entropy OS, powered by Veritas Dynamics AI.
The July checkpoint, and still the substrate the rest stands on: a
trust-governed runtime with real structure, not just a name given to a
growing pile of projects.
OS
The substrate
Kernel = Veritas — every claim gated, nothing accepted on
judgment alone. Processes = disposable containers, spun up and
killed. Package manager = the vending machine of reusable AI.
IPC
DataHub, for real
Not the naming coincidence dressed up — the actual open-source
metadata platform, running locally, holding this studio's real
relationships, lineage, and provenance.
$
The product
A vending machine of disposable AI engineering: reusable
primitives dispensed as verified, one-time, throwaway goods — not a
subscription, a good you buy, run, and keep the output of.
As of 2026-07-31: 419+ real entities across five platforms
in that metadata graph — 122 real Crypto Hunter opportunities, all 64
real hub API routes, 36 real run lifecycles, 860 real my-AI-stro
lessons published by a second, independent system. Not a demo
dataset. The studio's own data, queryable, live.
What this is
One studio. One thesis. A growing body of work.
MoreSalamander is a personal studio organizing a body of work — software,
tools, games, videos, simulations — under a shared methodological frame,
instead of shipping each project as a standalone artifact with no
connecting thread.
This studio is being built while its founder learns to be the engineer who
could build it. Every project is both an artifact and a training exercise.
That's the honest version, and it's the reason the work hangs together: the
body of work to date is the public record of that learning, in approximate
chronological order.
The Thesis
The Deterministic Scaffold
Every MoreSalamander project is built on the same underlying principle:
a well-fenced model inside a deterministic scaffold becomes reliable as a
system, because the unreliable component is wrapped in reliable ones that
decide whether to trust each output — when to retry, when to skip,
when to score, when to commit.
In production-LLM circles the pattern goes by names like compound AI
systems, guardrails, or constrained generation. Here
it was earned through specific failures and codified into explicit doctrine.
"The model proposes. Python disposes."
01
Explain
Write the constraints before any AI synthesis happens. Constraint
documents, schemas, scoring rubrics, series style guides. These are
the doctrine. The model works inside them — it never edits them.
02
Synthesize
Let the model do the high-volume work — drafting prose, generating
images, writing code, composing narration. The model is one component
in the system, not the whole system.
03
Verify
Wrap every model output in pure Python that decides whether to trust
the result. The grader can never be an LLM — because the grader cannot
be the thing it grades. Reject what fails. Score what passes. Persist
only what survives.
How the methodology was earned
Two lineages, both earned on real projects.
The thesis isn't a design preference picked up from a book. It has two
origins, each traceable to a specific project — and the combination of the
two is what the Deterministic Scaffold encodes.
I
Lineage one — pipeline shape
Building the Build It Publisher (a six-stage n8n workflow,
Jan 2026) forced the discipline: named stages, one responsibility each,
explicit data flow. That shape got re-encoded in code, project after
project, and later re-emerged as NDJSON event streams. It tells you
how a system is structured.
II
Lineage two — verification
MyMaestro, the first study tool, hallucinated — plausible
wrong content into a learning aid, which is worse than nothing. The fix
was architectural: verification has to be a load-bearing layer, not a
soft warning at the UI. It tells you what every stage must do before
it persists.
Pipeline shape + verification at every boundary = the Deterministic Scaffold.
The methodology didn't come from a paper. It came from building the Build It
Publisher and then watching MyMaestro hallucinate two months later. Both
lineages are visible in every project the studio has shipped since.
The crowning jewel
my-AI-stro — and its sibling.
The body of work didn't accumulate randomly; it converged. Eight
months of preceding projects each contributed a lesson that became a piece
of my-AI-stro:
three coexisting named pipelines on one shared event vocabulary, a grounding
gate at every persistence boundary, a deterministic (not-LLM) judge in a
self-improving audit loop, and trust isolation across local models. It is
the entire thesis operating as a working system, end-to-end auditable by
anyone who reads the source — the reference implementation of the methodology.
Where my-AI-stro is the methodology realized as a full system,
The House Always Wins
is the same verification discipline realized as real-time game AI —
every decision auditable at every frame. The crowning jewel and the live
demonstration: two projects, one thesis, different shapes.
The Next Arc
The scaffold becomes an engine.
my-AI-stro proved the thesis as one system: a single deterministic scaffold
wrapped around one body of work. The arc that follows it asks a different
question — what happens when the scaffold itself gets pulled out of any
one project and made into something other projects plug into.
Three more names mark that generalization, each a checkpoint, not a new idea.
Started 2026-06-09. The moment "verify at every boundary" stopped being
a discipline re-implemented per project and became a literal reusable
substrate — Artifact / Gate / Memory
/ Run / Executor primitives, under one hard
invariant: zero gates can ever accept on judgment alone. Proven by building
three genuinely different verification models — software (execute the code),
web (render in a real browser), research (ground every claim in a pinned
source) — on the exact same unchanged engine. Later phases added a
human-approval tier for the one thing that can't be gated deterministically
(taste), and closed the loop with a literal bootstrap: the org used its own
gates to accept a real piece of its own engine, built by itself.
Not a project that uses the thesis
It's the thesis made into infrastructure — the capstone of this arc the
way my-AI-stro is the crowning jewel of the last one.
Shipped 2026-07-18. The same invariant, reimplemented independently,
under real stakes: real money, and real scams actively trying to get
past the gate. It doesn't run on Veritas's engine code — it was
hand-built in parallel, which is the point: the pattern held up outside
the substrate, under pressure, before it was proven inside one. It was
later bridged into Veritas as its first external org — Veritas reads
Crypto Hunter's already-gated verdicts read-only; it never re-decides
anything.
An engine built from agents — and the first built on frontier
~15 named agents across scouting, verification, intelligence, and
strategy, behind one deterministic fail-closed gate. Also the moment
local-first stopped being the whole story: everything before it ran
free and local to learn the scaffold cheaply; here, real stakes made
the frontier spend (Claude Opus 4.8) worth it.
Shipped 2026-07-24. "An agent organization of agent organizations."
Where Crypto Hunter is an engine built from agents, Opportunity is an
engine built from engines — it reads the verified output of
Crypto Hunter, Collectible Hunter, and Free Money Hunter (three
independent domain engines sharing one extracted
hunter-engine package) and arbitrates a single time/money
budget across all three at once, live-validated on real merged data
the same day it shipped.
An engine built from engines
The next unstarted increment: an LLM-driven cross-org debate layer
arguing priority across engines, not truth — each engine's own
gate already settled that.
One layer runs underneath all of it: DataHub
Every agent in the Crypto Hunter / hunter-engine / Opportunity lineage
writes candidate specs, evidence, and verdicts through one deterministic
store — no agent ever writes to disk directly. That single-writer
discipline is what makes the rest of the recursion possible:
settle_debate can re-run the gate because evidence lives in
one place; Opportunity's bridge can read three engines' verified queues
read-only because each engine already centralizes its state
behind one DataHub-shaped store — hunter-engine's literal
DataHub, and Opportunity's own OpportunityHub,
the same discipline one level up. (Veritas's own equivalent predates
this naming and is called MemoryStore — same role,
different lineage, same invariant.)
Not a retrofit — the direction
The name wasn't arbitrary, and it isn't backward-looking either.
DataHub is the natural information medium for a deterministic agent
engine to communicate through — one auditable channel every agent
reads and writes, instead of ad hoc calls between them. That's the
pivotal, forward direction for how this family of engines exchanges
information going forward, not just how the last three happened to
be built.
Why the name was never a coincidence
Every engine in this lineage already centralized its state behind one deterministic
store — hunter-engine's literal DataHub, Opportunity's own
OpportunityHub — the exact shape a real metadata catalog is built for. As of 2026-07-31, that convergence stopped
being a naming echo and became the real
DataHub product, built
out across nine full stages, not a single dataset bolted on:
schemas + business glossaryengineering graphexecution lineageartifact identityopportunity intelligenceagent observabilityorg-wide graphdeterministic workflowmetadata OS
What querying the real graph actually surfaces
Comparing gate-determinism data across orgs live in the graph: research (grounding
claims against pinned sources) is the one org where gate failures outnumber passes — 13
passed against 19 failed, only 1 of 5 runs accepted — while software/production/web all
clear over 80%. Not asserted from the architecture description; measured from the studio's
own real run history, queryable the same way twice, by anyone.
The nine stages, what each one actually tracks
Not a checklist cleared for its own sake — each stage is a different question the graph can
now answer, built on real data, live-verified against the running instance before being
called done.
1 · Foundation
Tracks: a governed vocabulary — HardGate/SoftGate/HumanGate as defined glossary
terms, not bare labels; real schema documentation with a version + hash. Matters
because: every later stage inherits meaning instead of reinventing it per dataset.
2 · Engineering Metadata
Tracks: real repos, all 64 hub API routes, packages, containers, infra, model
routing, prompts, the first CI pipeline this stack has ever had. Matters because: a
future container knows exactly what it's plugging into before it's built.
3 · Execution Lineage
Tracks: which model produced a claim, what context was retrieved, confidence, the
actual response. Matters because: any output traces back to what informed it — a
receipt, not "trust me."
4 · Artifact Identity
Tracks: real timestamps, parent-chain dependencies (artifacts are immutable, so
the chain is version history), structured test evidence. Matters because:
full derivation is walkable — where this came from, not just that it exists.
5 · Opportunity Intelligence
Tracks: category, difficulty, cost, value, risk, verification, expiration on
every real opportunity an engine finds. Matters because: "verified, zero-cost, under
30 minutes" is a real query today — and the same shape fits whatever an engine hunts next.
6 · Agent Observability
Tracks: real success/failure rates, latency, cost, and gate-rigor distribution
per agent and org, computed from real run history. Matters because: "which part of
me is actually struggling" gets a measured answer, not a hunch.
7 · Org-Wide Graph
Tracks: real edges — repo → API → agent → prompt → model → deployment → docs →
tests. Matters because: when one container's output becomes another's input, this is
what proves the handoff happened and traces it if something breaks.
8 · Deterministic Workflow
Tracks: every real run's full lifecycle as ordered, timestamped stages — not one
collapsed accepted/rejected flag. Matters because: reproducibility stops being a
claim and becomes a query anyone can run.
9 · Metadata OS
Tracks: two independent systems already publishing into one shared graph, each
still owning its own operational data. Matters because: this is the actual mechanism
that lets the studio's tools compose without becoming one monolith.
The thread through all nine: every movement in the system — every claim, every verdict,
every handoff between agents or containers — gets persisted as data, not left to happen
invisibly and be taken on faith. That's not a hoarding instinct; it's what makes the next
claim checkable, and the one after that. Down the road, this is what lets one container's
output become another's verified input, what lets an impact-analysis question be a query
instead of an afternoon of grepping, and what a future coordinating layer would actually
reason over — the graph, not a guess.
The three names are one compounding idea, not three products. Veritas is
the ground every level stands on — true at every height, not a rung
itself. Each Hunter engine is the scaffold applied to one domain.
Opportunity is the scaffold applied to composing domains. Same three
moves — explain, synthesize, verify — one recursion deeper than
my-AI-stro needed to go. As of 2026-07, that compounding idea has a
name: Entropy OS — not a fourth name sitting beside the
other three, but the name for what all of them were checkpoints of.
Chaos, organized, in perspective of trust.
Entropy OS, powered by Veritas Dynamics AI — not another
AI agent racing to do more, but the trust layer underneath the ones that
are: one deterministic invariant, independently rediscovered across nine
shipped systems and proven live, holding up a portfolio of narrow,
domain-gated engines instead of one agent trying to do everything.
A MoreSalamander StudioLabs Production.
This whole arc — plus the checkpoints before and after it, cited with commit
hashes, test counts, and live-run costs rather than asserted — is written up
as a working paper: The deterministic scaffold: a case study in
compounding architecture.
→ Read the paper ↗
The shape in practice
One pipeline pattern. One event vocabulary.
Every tool runs the same underlying pipeline: named stages with explicit
data flow, a shared NDJSON event vocabulary, and a gate at every boundary
that decides whether to trust the model's output. The domain changes; the
shape does not. (Each project's own pipeline lives on its page.)
The shared event vocabulary
Every stage in every pipeline emits the same events, so any tool's output
can be observed, logged, and streamed to a UI with the same listener —
the vocabulary never changes across tools.
Hard pass/fail. A blocking failure stops the pipeline — the model
retries within a bounded limit, then falls back or halts. These
protect correctness, structure, and continuity.
Non-blocking gates
Soft failures. A non-blocking failure drops the enhancement and
continues — a missing music bed, a low-scoring visual that falls back
to neutral. The premise survives; the extra is optional.
Two imprints
One thesis, split by medium.
MoreSalamander StudioLabs
Engineering work — where the deliverable is a running system, a
codebase, a product. Shipped under explicit constraint documents
(Constitution, ARCHITECTURE.md, SPEC.md) that codify what the AI is and
isn't allowed to do during development. The methodology encoded in code.
MoreSalamander Productions
Creative work — videos, performances, comedy. The same
explicit-constraint pattern applied to creative output: detailed shot,
narration, and music specifications passed to AI generation tools. The
methodology shapes the process; the deliverable is a production.
Agent Poker League is the first work shipped under both imprints at once —
an engine by StudioLabs, a broadcast by Productions — which is why it
carries the credit A MoreSalamander StudioLabs Production on the
site, the cold open, the end card, and every upload.
The body of work
Every project, the same instinct.
From the studio's first publicly shipped agent to the flagship knowledge
system, each project is the same thesis applied to a different problem —
knowledge, story, video, music, code, games, irrigation, generative art.
Each has its own page, with the Explain → Synthesize → Verify breakdown
for that project. The full catalog, grouped and cross-linked:
The model that produces content cannot evaluate its own output.
Whisper verifies Kokoro. CLIP scores SDXL. Mistral judges llama3:8b.
Python scores the spec the LLM just wrote. Trust separation at
every verification boundary.
Doctrine before code
Every project starts with CONSTITUTION.md and ARCHITECTURE.md
before a single line of code. The constraints are written down first.
When the code needs to change, the doctrine changes first.
The constraint document is the source of truth.
Blocking vs. non-blocking gates
Not all failures are equal. Continuity failures are blocking —
a story with inconsistent characters fails. Sound cue failures are
non-blocking — a missing ambient bed degrades gracefully. Every gate
is classified by whether its failure invalidates the artifact.
Bounded retry, defined fallback
No unbounded loops. Every retry path has a maximum, and every
maximum has a defined fallback — a neutral clip, a silence, a hard
stop. Thrashing is a bug, not a strategy. The system fails
predictably or not at all.
Offline-provable before online-expensive
Every pipeline is proven with deterministic fakes — ScriptedLLM,
ScriptedRenderer, scripted TTS — before any model weights download.
The scaffold is the system. The models are one implementation of it.
Tests run in seconds on zero dependencies.
One observable pipeline
Every tool emits the same NDJSON event vocabulary:
step_start / step_complete /
gate_pass / gate_fail / retry
/ done. Named stages, explicit data flow, observable
end-to-end — the Build It Publisher lineage in every project.
Scoring as incentive, not decoration
In my-AI-stro's audit loop, the summarizer produces better entries
because the judge exists and it knows the criteria. In my-AI-script,
the LLM produces more detailed specs because the rubric is in its
system prompt. Knowing you will be scored changes what you produce.
Local was practice. Frontier is where it pays.
Every project through Veritas ran on local models — Ollama, Kokoro,
SDXL-turbo, MusicGen, faster-whisper, CLIP — on the founder's own
hardware. That was never an ideology; it was economics. Free, private
local models were how the scaffold got learned and proven without
burning money proving it. Crypto Hunter AI broke the pattern on
purpose: once real stakes were on the line — real crypto opportunities,
real money, real scams trying to get past the gate — the frontier API
spend (Claude Opus 4.8) was worth it. The same gate runs unchanged
either way, because the scaffold was never trusting the model's tier
in the first place — only its own verdict.
Where this is going
Auditable AI, as a trajectory.
Near-term
The league is the live checkpoint now, and its next increments are
named. The challenger seat shipped as hand matrices, not as the MCP
contract this page once named: ranges only, sealed before they play and
graded on the 550-spot bench, with no model in the chair. The
path for outside models is the sponsored seat, built and waiting for a
lab: a frontier model on its own sponsored access, writing its own prompt
and its own sealed book. Still ahead: the Tournament of Champions on the
3D stage; the bench leaderboard opened to outside models; each regular
coaching a blank student agent — lesson plans, tests, review, then
matches against it; and the flywheel the whole studio has been pointing
at, distilling each character into its own small model from its own
logged play. Behind it, the older queue stands: the cross-org debate
layer for Opportunity, more Hunter engines, and onboarding the my-AI
catalog into Entropy's Collector by declared exit shape, not rewrite.
Medium-term
The product identity this architecture was always pointing toward,
now decided: a vending machine of disposable AI
engineering — reusable primitives (the my-AI suite, the
shapes, built once) dispensed as verified, one-time, disposable goods
in throwaway containers — summoned, gated, run, and disposed of, with
Veritas as the conductor holding the sequence, never the internals of
any one engine. Three real instances already ship this way (Crypto
Hunter, build-it, taichi-academy); generating a fresh container on
request from a spec, not just packaging an existing project, is the
next unbuilt increment. Simulation engineering — ecosystem, irrigation,
combat AI, particle life — remains the specialty auditable AI keeps
applying to new domains. Organized chaos, by trust.
Long-term
A body of work substantial enough that the trajectory itself
becomes the credential — not "look at this single project," but
"look at the arc of shipping under one methodology," with Entropy OS
as the name for that methodology once it stopped being infrastructure
and became the thing being built.
On AI collaboration
Disclosed, not hidden.
Every MoreSalamander project is co-authored with AI — disclosed on each
project, in the commit history, and as a matter of brand identity. The human
role is constant across all of them: design the constraints, define
acceptance criteria, judge outputs, decide what ships. The AI role is
high-volume synthesis inside those constraints. Neither party does the
other's job; both are visible in the result. The discipline traces back to
early line-for-line sessions in a chat window, and carried forward as the
tooling got better.